• Skip to primary navigation
  • Skip to main content
  • Skip to primary sidebar

Meet Ashwin

Helping Engineers To Become Tech Leaders

  • Blog
  • Newsletter
  • Courses
    • Generative AI 101
    • LLMOps 101
    • Data Platforms Made Easy
  • Products
    • Generative AI Ecosystem Mindmap
    • 8 Mistakes to avoid in Tech Leadership (e-book)
  • Resources
  • Contact

aiagents

AI Tokenomics: How to Cut Down on Agent Costs by Measuring Them Right

October 17, 2026 by Ashwin Leave a Comment

Your AI demo cost pennies. Your AI product may not. A pilot that answers a few hundred questions a day looks almost free, but put the same design in front of thousands of users, let it call tools and loop on its own, and the invoice changes character.

The reason is one small word: tokens. Tokens are the pieces of text an AI model reads, writes and bills by. In the agentic era they are also the unit of cost, speed and capacity. This post explains what tokenomics is, why it suddenly matters, and what you can do about it, in plain language.

Short on time? Read the TL;DR version of this post.

What is Tokenomics?

    Tokenomics is the economics of AI tokens: how many a task uses, what each one costs, and what you get in return. (It has nothing to do with crypto here.) Cisco frames it for agents as measuring and optimizing the cost, value and efficiency of token consumption.

    A token is a small chunk of text, roughly three-quarters of a word in English. Think of it as a taxi meter for thinking: the meter runs every time the model reads or writes. Five terms cover most of what you need:

    • Input tokens: what you send in, including your question, instructions and any documents.
    • Output tokens: what the model writes back. These cost more.
    • Context window: how much the model can hold in view at once.
    • Cached tokens: input the provider has already processed, billed at a discount.
    • Reasoning tokens: the model’s internal “thinking”, billed like output even if you never see it.

    What tokens cost today

    Prices are quoted per million tokens. As of 15 October 2026, BenchLM’s tracker of official API rates shows a 100-fold spread between the cheapest and the priciest models listed, and output costs five times input in every row below.

    ModelTierInput ($ per 1M tokens)Output ($ per 1M tokens)
    Claude Haiku 5.5Budget0.100.50
    Claude Sonnet 5.5Mid-range2.0010.00
    GPT-6 SolMid-range2.0010.00
    Claude Opus 5.5Premium4.0020.00
    GPT-6 AstraFrontier10.0050.00
    Claude Fable 5.1Frontier10.0050.00

    Prices change often, so check the provider before you budget.

    The real metric is cost per task

    Per-token prices alone mislead, because tasks use very different numbers of tokens. A quick, illustrative sum: a support agent that reads 40,000 tokens and writes 4,000 to resolve one ticket, on a $2 / $10 model, costs 8 cents for input plus 4 cents for output, so 12 cents. At 100,000 tickets a month, that is $12,000.

    This is why Cisco’s framework tracks “cost per resolution” and “token yield”, meaning successful task completions per million tokens, rather than price per token.

    Why it is becoming critical

    Agents multiply tokens, and cheaper tokens have not made bills smaller. Four forces are behind it.

    1. Agents loop. A chatbot answers once. An agent plans, calls tools, checks the result and tries again. Gartner estimates agentic tasks need 5 to 30 times more tokens than a standard chatbot exchange. One reported fraud-check example used about 13,500 tokens against 800 for a basic chat, roughly 17 times more, according to Spheron’s review of agentic inference costs.

    2. The context snowball. At every step the agent re-sends everything so far: instructions, tool descriptions and earlier results. The same review reports Stanford findings that coding agents can use up to 1,000 times the tokens of a simple chat, mostly on input, and that identical agents on identical tasks differed by up to 30 times in cost.
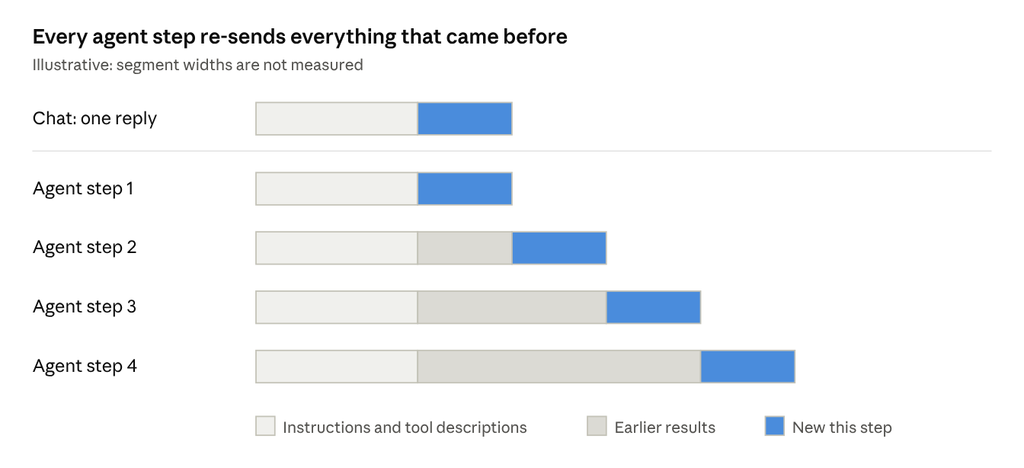
    Context snowball · illustrative, 1 chat reply and 4 agent steps

    A chat reads the conversation once. In an agent loop, every block is billed again on each call, so each extra step costs more than the one before.

    3. Reasoning is billed. Reasoning models “think” before they answer, and those hidden tokens are charged. Cisco notes that cost per million tokens has fallen by over 99% in recent years, yet reasoning is expected to push total inference spend up.

    4. Pilots hide the problem. A prototype serves few users with easy cases. Production adds retries, edge cases and power users. Spheron reports that Uber’s Claude Code spend averaged $150 to $250 per engineer per month, with heavy users at $500 to $2,000, which led to a cap of $1,500 per employee per tool.

    Falling prices are not the whole story

    Unit prices are dropping fast. Epoch AI found that the price of reaching a fixed capability level fell between 9 and 900 times per year, depending on the benchmark, and warned the fastest drops may not last. But when one task uses 5 to 30 times more tokens, volume can outrun the discount.

    For enterprises this is also a governance question: who owns the budget, how spend is attributed to teams, and how to keep costs predictable when an agent’s number of steps cannot be known in advance.

    Design elements that keep token use in check

    Good tokenomics is mostly design, not discount hunting. Nine levers, roughly in order of payoff:

    1. Route by difficulty. Send easy steps to a small, cheap model and keep the frontier model for hard ones. In the price table above, the budget model costs 20 times less on input than a mid-range one. MindStudio estimates task-based routing saves 40 to 70%, though that is the author’s estimate, not a measured study.
    2. Cache what repeats. Instructions and reference text that never change can be cached. On Anthropic’s API, cache reads cost 10% of the base input price on most models and 5% on Claude Sonnet 5.5 and Opus 5.5. One reported case study cut LLM cost 59% by lifting its cache hit rate from 7% to 84%, per Spheron.
    3. Trim the context. Send only what the step needs. Retrieve the relevant snippet instead of the whole document, and summarize old conversation history.
    4. Put tools on a diet. Every tool description is re-sent on every call. Cisco reports that loading only the tool definitions a sub-task needs has cut token use by over 98% in some cases. Keep tool outputs short and structured too.
    5. Package know-how as skills. A skill loads just its name and description until the task needs it, instead of stuffing every instruction into every request.
    6. Cap the loop. Set a maximum number of steps, tokens and retries per task, and stop gracefully. Spheron notes that retries can outweigh the rest of a task’s token cost.
    7. Batch the non-urgent. An overnight report does not need an instant answer. Providers offer batch processing at a lower price for work that can wait.
    8. Measure everything. Meter tokens per agent, per task and per team. Track cost per resolution and token yield, not just the monthly total.
    9. Add guardrails. Budgets, alerts and circuit breakers stop a runaway agent before the invoice does.
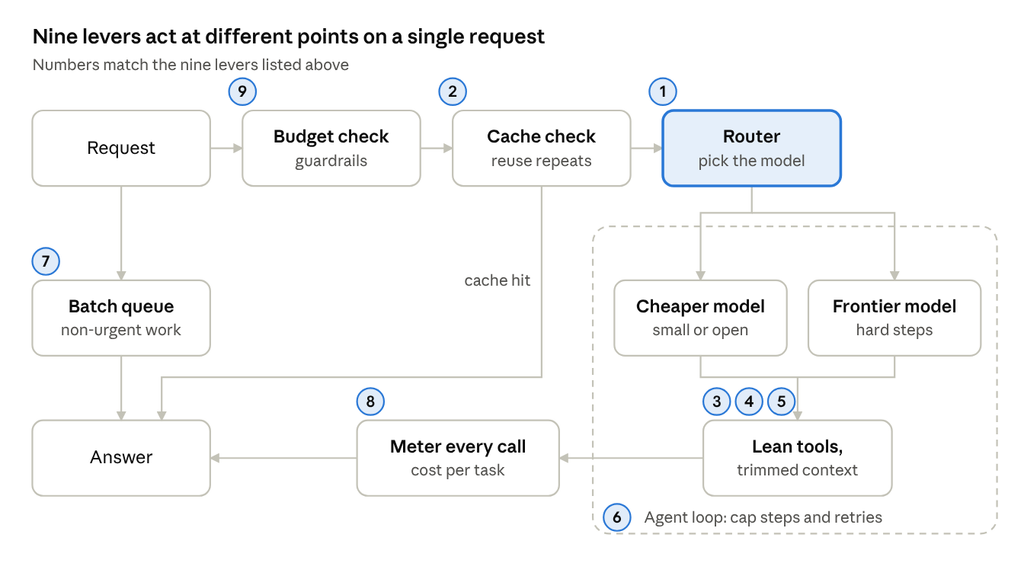
    Where each lever acts · one request, 9 levers

    Read it from the top left: guardrails and the cache can stop or answer a request before any model is called, the router sends each step to the cheapest model that can handle it, and the loop stays inside a cap.

    How open-weight and open-source models help

    Open-weight models publish their trained “weights”, so anyone can download and run them, or pick from many hosting companies. Strictly “open source” also shares training code and data, which is rarer. For tokenomics the practical point is the same: you gain a choice over who runs the model and what it costs.

    Price and quality, side by side

    OpenRouter’s June 2026 review of the open-weight models that matter lists these average prices and Artificial Analysis Intelligence Index scores (higher is better):

    Open-weight modelIntelligence IndexInput ($ per 1M tokens)Output ($ per 1M tokens)
    DeepSeek V4 Flash400.0540.242
    MiniMax M3440.0981.21
    Nemotron 3 Ultra480.4232.61
    GLM 5.2510.4473.31

    The same article puts the top open model, GLM 5.2, about 5 points below Claude Fable 5 on that index. It also reports DeepSeek V4 Pro at 80.6% on SWE-bench Verified, a coding test, which it calls on par with GPT-5.5-class models. Against the price table earlier, DeepSeek V4 Flash’s first-party output rate of $0.28 per million tokens is about 180 times below Claude Fable 5.1’s $50.

    Two caveats from that review: DeepSeek’s own API retains and trains on user data, and Western hosts that do not train on your data charge about double.

    Same workload, very different bills
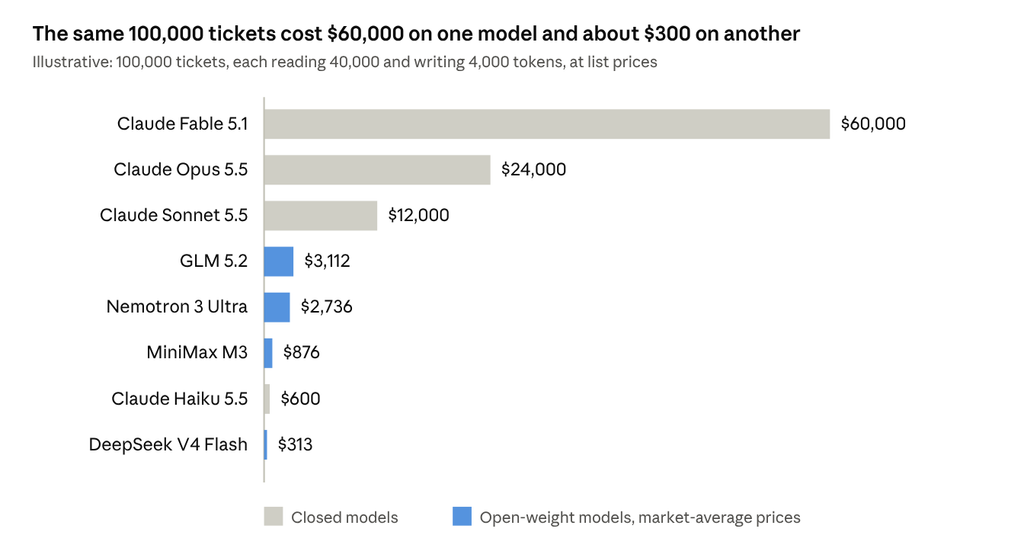
    Illustrative cost · list prices from BenchLM (15 Oct 2026) and OpenRouter (June 2026), 8 models

    The chart reuses the support ticket from earlier. Quality is not equal across these models and open-weight prices are market averages, so read it as a sense of scale, not a buying guide.

    Where they help

    • Lower unit cost. The table speaks for itself, especially for high-volume work.
    • Right-sizing. A small model can classify emails or extract fields for a fraction of a frontier model’s price, which pairs well with routing.
    • Control. Running a model in your own cloud keeps sensitive data in-house, which matters in regulated industries.
    • Predictable spend. Self-hosting turns a per-token meter into an infrastructure cost, easier to budget when traffic is steady.
    • Efficiency tuning. You can apply caching, batching and model compression yourself, rather than waiting for a provider to.

    Read the fine print

    Cheaper per token is not always cheaper per task. In an example from investor Bindu Reddy, reported by MindStudio, Kimi K3 costs about half of GPT 5.1 per token but needs more tokens, so a completed task costs 84 cents against 96 cents, only about 12.5% less.

    Self-hosting has its own bill. Layer3 Labs warns that idle rented GPUs quietly drain budgets, that engineering time is often the largest yearly line item, and that you should stress-test costs at 30 to 50% GPU utilization, not 100%. Benchmarks also vary: the gap to closed models is small on some coding and knowledge-work tests and wider on the hardest reasoning tasks.

    The hybrid pattern

    Most teams land on a mix. Open models handle high-volume, well-defined work, frontier models handle the hardest steps, and a router decides between them. It is the routing idea from the previous section with a wider menu.

    A simple framework to get started

    You do not need to do all nine levers at once. Start with five steps you can finish in a week:

    1. Measure. Count tokens and cost for one real workflow, end to end. Work out the cost per completed task, not per call.
    2. Route. Pick the easiest third of the steps and test a cheaper model on them. Keep the better model for the rest.
    3. Trim. Look at what you send on each call. Cut instructions, history and tool descriptions that the step does not need.
    4. Cache. Move the unchanging parts, such as instructions and reference text, to the front and turn on caching.
    5. Cap. Set a limit on steps, retries and spend per task, with an alert when it is close.
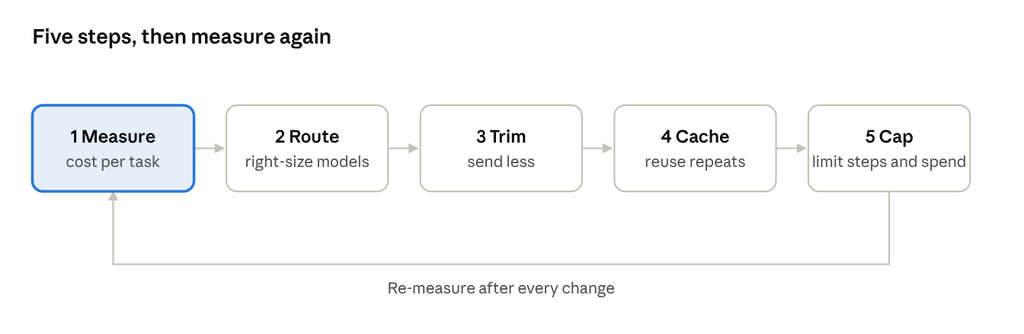
    Getting-started cycle · 5 steps, 1 loop

    Re-measure after each step. The goal is a lower cost per successful outcome with quality held steady, not the smallest token count.


    TL;DR

    • What Tokenomics covers: Tokenomics is the economics of AI tokens—how many tokens a task uses, what each costs, and what you get in return, framed as cost, value and efficiency of token consumption.
    • What a token is and the key types: A token is a small chunk of text; the main types are input tokens, output tokens, context window, cached tokens, and reasoning tokens, each contributing to cost.
    • The real metric: cost per task: Prices per token miss the bigger picture; cost per resolution or per task accounts for token usage across a workflow and is the practical measure of spending.
    • Why tokenomics is becoming critical: Agentic systems loop, the context snowball grows with every step, reasoning is billed, and pilots hide the problem, all driving token usage higher in production.
    • A simple starting framework to reduce token use: Start with five steps: measure cost per task, route easy steps to cheaper models, trim unnecessary input, cache unchanging content, and cap the loop with limits and alerts.

    The Takeaway

    Design for cost per outcome from day one. Cheaper tokens help, but they do not replace good design: route work to the right model, send less, reuse what repeats, and put a ceiling on every agent. Teams that treat tokens like any other scarce resource will scale agents with confidence, and the rest will scale surprises.

    What is the first workflow in your organization where you would measure cost per task? A worked cost model for a real agent would make a good follow-up.
    Filed Under: AI Agents, Data & AI, Tokenomics Tagged With: agents, ai, aiagents, data, tokenomics, tokens

    Enterprise AI Agents: Why Governance is Your Competitive Advantage

    December 13, 2025 by Ashwin Leave a Comment

    Building AI agents in an enterprise extends far beyond prototypes and POCs. When designing agents for real users who drive revenue, governance becomes critical.

    This post explores the essential governance pillars for integrating AI agents into enterprise production applications. 

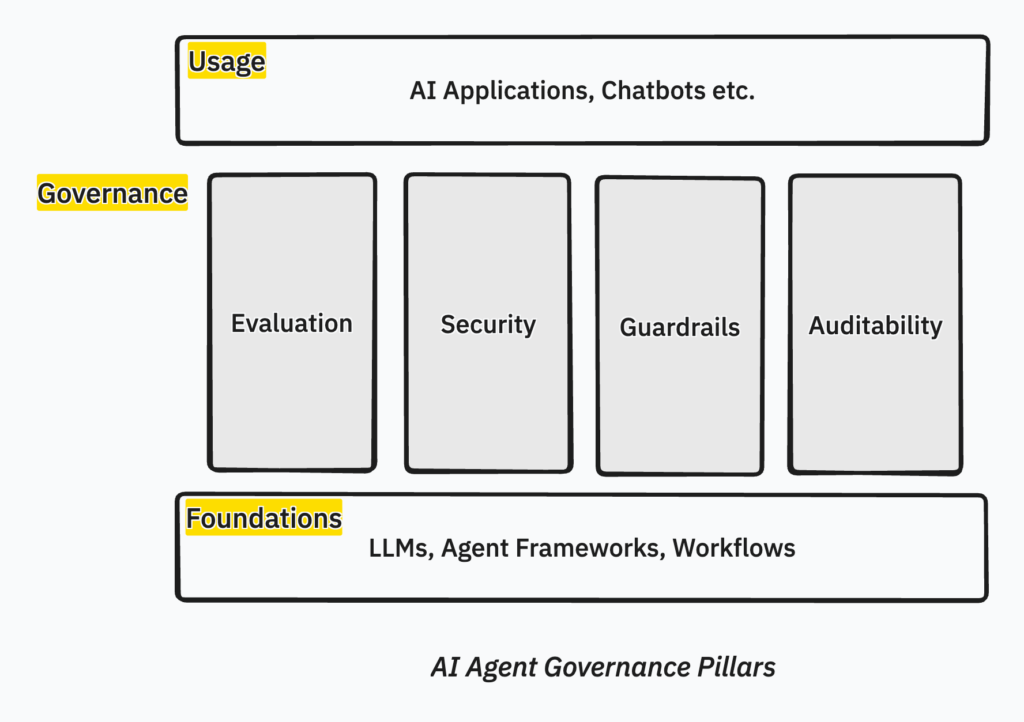
    In the world of Agent Management Platforms, four governance pillars strengthen the successful rollout of AI agents in your organization.

    Short on time? Check the TL;DR

    Pillars of AI Agents Governance

    AI Agents Governance Pillars
    • Evaluation – How do you evaluate the correctness and completeness of agent outputs
    • Security – How do you protect agents against malicious attacks and breaches
    • Guardrails – How do you set boundaries and checkpoints, often tied to your business and compliance rules
    • Auditability – How do you understand everything that has gone on before an agent produced the outputs

    For this article, I will pick examples of each pillar from the open-source CrewAI Agentic framework.  But you can essentially implement it with other similar frameworks like LangGraph, Mastra, etc.


    AI Agents Evaluation

    Evaluation in AI agent systems serves a similar purpose to testing in traditional software development—validating that the system performs as intended. 

    However, AI agents built on large language models are non-deterministic systems. Unlike conventional software, where the same input consistently produces the same output, AI agents may generate different responses across multiple runs. This variability requires specialized evaluation approaches.

    Understanding Non-Deterministic Behavior

    The non-deterministic nature of LLM-based agents stems from temperature settings, sampling methods, and the probabilistic nature of language generation. 

    While this enables creative problem-solving and natural interactions, it means traditional unit tests with exact output matching are insufficient. Instead, evaluation must assess whether outputs meet quality standards and functional requirements rather than matching predetermined values.

    Two Complementary Evaluation Approaches

    Effective AI agent evaluation employs two methodologies: subjective and objective evaluation.

    Subjective Evaluation: LLM-as-Judge

    Subjective evaluation leverages other LLMs to review, critique, and score agent outputs. This approach assesses qualities difficult to measure programmatically, such as relevance, coherence, helpfulness, and tone. 

    An LLM judge evaluates whether an agent’s response appropriately addresses the user’s intent, maintains a consistent persona, or demonstrates sound reasoning.

    The judge receives the original task, the agent’s output, and specific evaluation criteria. It then generates a critique and assigns scores, revealing subtle issues like logical inconsistencies or inappropriate confidence levels that traditional metrics might miss.

    Objective Evaluation: Gold Standard Comparison

    Objective evaluation relies on gold standard datasets—curated collections of inputs paired with known correct outputs. The process compares agent outputs against these benchmarks using quantifiable metrics such as accuracy, precision, recall, or task-specific success criteria.

    For example, if an agent extracts structured information from documents, objective evaluation measures how accurately it identifies required fields compared to human-annotated examples. 

    For multi-step workflows, evaluation verifies that the agent completes all necessary steps in the correct sequence.

    Implementation in Practice

    Modern agent frameworks like CrewAI provide built-in evaluation capabilities combining both approaches. 

    A typical workflow includes running the agent multiple times with the same test cases, applying LLM judges for subjective quality assessment, comparing outputs against gold standards, and aggregating results to identify patterns and issues.

    Evaluation results inform iterative improvement. Teams can adjust agent instructions, refine prompts, modify tool configurations, or retrain components based on performance gaps. This continuous evaluation and refinement process is essential for maintaining reliable AI agent systems in production.


    AI Agents Security

    AI agents face unique security challenges that differ from traditional software vulnerabilities. As agents interact with users, access tools, and process data autonomously, they become targets for malicious attacks designed to manipulate their behavior or extract sensitive information.

    Common Security Threats

    Prompt Injection occurs when attackers craft inputs that override an agent’s original instructions, causing it to ignore safety guidelines or perform unintended actions. These attacks exploit the agent’s natural language interface to introduce malicious directives disguised as legitimate requests.

    Tool Misuse happens when agents are manipulated into using their capabilities inappropriately—such as accessing unauthorized data, executing harmful commands, or making API calls that violate business rules. Since agents have direct access to tools and systems, compromised decision-making can have immediate consequences.

    Data Poisoning involves corrupting the training data or knowledge bases that agents rely on, causing them to learn incorrect patterns or biased behaviors. Attackers may inject false information into retrieval systems or databases that agents query.

    Context Poisoning targets the agent’s working memory by inserting misleading information into conversation history or retrieved documents. This can cause the agent to make decisions based on false premises or manipulated context.

    Identity Spoofing exploits weak authentication mechanisms, allowing attackers to impersonate legitimate users or systems. Agents may then grant unauthorized access or perform actions on behalf of fake identities.

    Security Countermeasures

    Protecting AI agents requires multiple defensive layers. Input validation and sanitization filters suspicious patterns before they reach the agent’s core reasoning. Output monitoring detects when responses deviate from expected behavior or contain sensitive information leaks.

    Tool access controls implement permission boundaries, ensuring agents can only invoke authorized functions with appropriate parameters. Context isolation separates user inputs from system instructions, making it harder for malicious prompts to override core directives.

    Authentication and authorization frameworks verify user identities and enforce role-based access controls before agents process requests. Audit logging tracks all agent interactions, tool usage, and decision points for forensic analysis and compliance.

    Adversarial testing proactively simulates attacks to identify vulnerabilities before deployment. Security-focused evaluation frameworks can test agent resilience against known attack patterns and edge cases.

    Modern agent platforms are increasingly incorporating these security primitives as built-in features, but organizations must still configure them appropriately and maintain vigilance as new attack vectors emerge.


    AI Agents Guardrails

    AI agents operating autonomously in production environments require guardrails—protective boundaries that ensure safe, compliant, and aligned behavior. Unlike traditional software with hardcoded logic paths, agents make dynamic decisions that need real-time constraints to prevent harmful or inappropriate actions.

    Types of Guardrails

    Input Guardrails filter and validate incoming requests before they reach the agent’s reasoning engine. These prevent processing of prohibited content, malicious prompts, or queries outside the agent’s intended scope. Input guardrails can reject requests containing personal identifiable information (PII), offensive language, or topics the agent shouldn’t address.

    Output Guardrails scan agent responses before delivery to users, blocking content that violates policies or quality standards. These catch hallucinations, inappropriate recommendations, leaked sensitive data, or responses that contradict business rules. Output guardrails ensure the agent doesn’t make unauthorized commitments or provide advice beyond its mandate.

    Behavioral Guardrails constrain how agents use tools and make decisions during execution. These include spending limits on API calls, restrictions on which databases can be accessed, approval requirements for certain actions, and constraints on autonomous decision-making scope. For example, an agent might require human approval before financial transactions exceed a threshold.

    Contextual Guardrails adapt constraints based on user roles, conversation context, or operational conditions. An agent might have different permissions for internal employees versus external customers, or operate under stricter rules during high-risk scenarios.

    Implementation Approaches

    Guardrails can be implemented through rule-based systems that enforce explicit policies, LLM-based classifiers that evaluate content against nuanced criteria, or hybrid approaches combining both. Modern agent frameworks provide guardrail APIs that intercept agent workflows at key checkpoints—before tool execution, after response generation, and during multi-step reasoning chains.

    Effective guardrails balance safety with functionality. Overly restrictive guardrails frustrate users and limit agent utility, while insufficient guardrails expose organizations to risk. Continuous monitoring and adjustment ensure guardrails remain calibrated to organizational needs.


    AI Agents Auditability

    Auditability establishes transparency and accountability for AI agent operations. As agents make autonomous decisions that impact business outcomes, organizations need comprehensive records of what agents did, why they did it, and what information influenced their decisions.

    Essential Audit Components

    ComponentWhyWhat to capture?

    Decision Trails
    Understand why an agent reached a particular conclusion or took a specific action.Capture the agent’s reasoning process, including which tools were invoked, what information was retrieved, how the agent weighted different factors, and what alternatives were considered.

    Interaction Logs
    To understand the complete context of each interaction, supporting compliance reviews, quality assurance, and issue resolutionAll user inputs, agent outputs, and conversation flows.Logs should include timestamps, user identifiers, session metadata, and any relevant business context.

    Tool Usage Records
    For security monitoring, cost management, and understanding the agent’s operational footprint across enterprise systems.Document every external system call, API request, database query, and file access performed by the agent.

    Performance Metrics
    Identify patterns that indicate degraded performance, emerging issues, or opportunities for improvement.Track success rates, response times, error frequencies, and user satisfaction scores.

    Compliance and Governance

    Auditability supports regulatory compliance by providing evidence of proper agent behavior. Industries with strict oversight—such as finance, healthcare, and legal services—require detailed records demonstrating that agents operated within approved parameters and didn’t make unauthorized decisions.

    Audit data also enables retrospective analysis when issues arise. If an agent provides incorrect information or makes a problematic decision, audit trails allow teams to reconstruct the event, identify root causes, and implement corrective measures.

    Implementation Considerations

    Effective audit systems must balance comprehensiveness with storage and privacy concerns. Logs should capture sufficient detail for meaningful analysis while protecting sensitive information. Retention policies should align with regulatory requirements and business needs.

    Modern agent platforms provide structured logging frameworks that automatically capture key events in standardized formats. Organizations should integrate these logs with existing observability and compliance systems, enabling centralized monitoring and analysis across all AI agent deployments.


    Conclusion

    AI agents represent a fundamental shift in how enterprises deliver value—moving from deterministic software to autonomous systems that reason, decide, and act on behalf of organizations. This power comes with responsibility. Without robust governance, agents can make costly mistakes, expose sensitive data, violate policies, or erode user trust.

    The four governance pillars—evaluation, security, guardrails, and auditability—form an integrated framework for deploying AI agents safely and effectively in production environments.

    Evaluation ensures agents perform reliably despite their non-deterministic nature, combining subjective LLM-based assessment with objective benchmarking to validate quality before and after deployment.

    Security protects against emerging threats unique to AI systems, from prompt injection to identity spoofing, implementing defensive layers that safeguard both the agent and the systems it accesses.

    Guardrails establish boundaries that keep agents aligned with organizational policies and ethical standards, constraining behavior without sacrificing the flexibility that makes agents valuable.

    Auditability provides transparency into agent operations, creating decision trails that support compliance, enable root cause analysis, and build stakeholder confidence in autonomous systems.

    Together, these pillars transform AI agents from experimental prototypes into trustworthy enterprise tools. Organizations that invest in governance upfront accelerate adoption, reduce risk, and unlock the full potential of AI agents to drive business value. As agents become more capable and autonomous, governance won’t be optional—it will be the foundation of successful AI implementation.

    Filed Under: AI, AI Agents, Data & AI, Tech Tagged With: agent governance, agents, ai, ai agents, aiagents, data

    Primary Sidebar

    Connect with me on

    • GitHub
    • LinkedIn
    • Twitter

    Recent Posts

    • AI Tokenomics: How to Cut Down on Agent Costs by Measuring Them Right
    • A Weekend with OpenClaw : Musings and Learnings
    • Agent Evals 101 : Building a Strong Evaluation Framework for AI Agents
    • Enterprise AI Agents: Why Governance is Your Competitive Advantage
    • How Do LLMs Work? A Simple Guide for Kids, Teens & Everyone!
    • Topics

      • Data & AI
        • AI Agents
        • Tokenomics
      • Life
        • Leadership
        • Negotiations
        • Personal Finance
        • Productivity
        • Reading
        • Self Improvement
      • Post Series
        • Intro to Blockchain
      • Tech
        • AI
        • Blockchain
        • Career
        • Certifications
        • Cloud
        • Data
        • Enterprise
        • Generative AI
        • Leadership
        • Presentations
        • Reporting
        • Software Design
        • Stakeholders
      • Uncategorized

    Top Posts

    • A Weekend with OpenClaw : Musings and Learnings
    • Leading with Action
    • Event-driven Systems
    • Understanding the Paradigm of AI Tools, Apps and Agents
    • Create your first NFT with Smart Contract

    Copyright © 2026 · Ashwin Chandrasekaran · WordPress · Log in
    All work on this website is licensed under a Creative Commons Attribution-ShareAlike 4.0 International License
    The views and opinions expressed in this website are those of the author and do not necessarily reflect the views or positions of the organization he is employed with