Your AI demo cost pennies. Your AI product may not. A pilot that answers a few hundred questions a day looks almost free, but put the same design in front of thousands of users, let it call tools and loop on its own, and the invoice changes character.
The reason is one small word: tokens. Tokens are the pieces of text an AI model reads, writes and bills by. In the agentic era they are also the unit of cost, speed and capacity. This post explains what tokenomics is, why it suddenly matters, and what you can do about it, in plain language.
Short on time? Read the TL;DR version of this post.
What is Tokenomics?
Tokenomics is the economics of AI tokens: how many a task uses, what each one costs, and what you get in return. (It has nothing to do with crypto here.) Cisco frames it for agents as measuring and optimizing the cost, value and efficiency of token consumption.
A token is a small chunk of text, roughly three-quarters of a word in English. Think of it as a taxi meter for thinking: the meter runs every time the model reads or writes. Five terms cover most of what you need:
- Input tokens: what you send in, including your question, instructions and any documents.
- Output tokens: what the model writes back. These cost more.
- Context window: how much the model can hold in view at once.
- Cached tokens: input the provider has already processed, billed at a discount.
- Reasoning tokens: the model’s internal “thinking”, billed like output even if you never see it.
What tokens cost today
Prices are quoted per million tokens. As of 15 October 2026, BenchLM’s tracker of official API rates shows a 100-fold spread between the cheapest and the priciest models listed, and output costs five times input in every row below.
| Model | Tier | Input ($ per 1M tokens) | Output ($ per 1M tokens) |
|---|---|---|---|
| Claude Haiku 5.5 | Budget | 0.10 | 0.50 |
| Claude Sonnet 5.5 | Mid-range | 2.00 | 10.00 |
| GPT-6 Sol | Mid-range | 2.00 | 10.00 |
| Claude Opus 5.5 | Premium | 4.00 | 20.00 |
| GPT-6 Astra | Frontier | 10.00 | 50.00 |
| Claude Fable 5.1 | Frontier | 10.00 | 50.00 |
Prices change often, so check the provider before you budget.
The real metric is cost per task
Per-token prices alone mislead, because tasks use very different numbers of tokens. A quick, illustrative sum: a support agent that reads 40,000 tokens and writes 4,000 to resolve one ticket, on a $2 / $10 model, costs 8 cents for input plus 4 cents for output, so 12 cents. At 100,000 tickets a month, that is $12,000.
This is why Cisco’s framework tracks “cost per resolution” and “token yield”, meaning successful task completions per million tokens, rather than price per token.
Why it is becoming critical
Agents multiply tokens, and cheaper tokens have not made bills smaller. Four forces are behind it.
1. Agents loop. A chatbot answers once. An agent plans, calls tools, checks the result and tries again. Gartner estimates agentic tasks need 5 to 30 times more tokens than a standard chatbot exchange. One reported fraud-check example used about 13,500 tokens against 800 for a basic chat, roughly 17 times more, according to Spheron’s review of agentic inference costs.
2. The context snowball. At every step the agent re-sends everything so far: instructions, tool descriptions and earlier results. The same review reports Stanford findings that coding agents can use up to 1,000 times the tokens of a simple chat, mostly on input, and that identical agents on identical tasks differed by up to 30 times in cost.
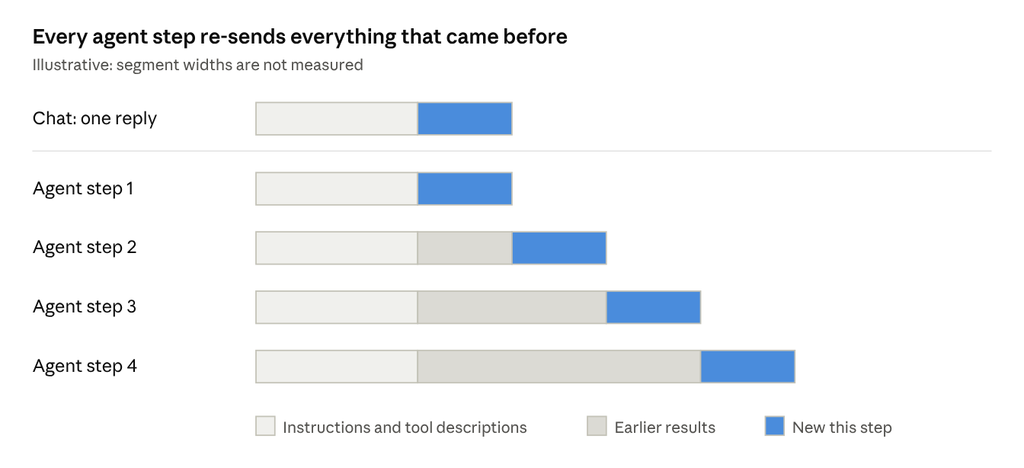
A chat reads the conversation once. In an agent loop, every block is billed again on each call, so each extra step costs more than the one before.
3. Reasoning is billed. Reasoning models “think” before they answer, and those hidden tokens are charged. Cisco notes that cost per million tokens has fallen by over 99% in recent years, yet reasoning is expected to push total inference spend up.
4. Pilots hide the problem. A prototype serves few users with easy cases. Production adds retries, edge cases and power users. Spheron reports that Uber’s Claude Code spend averaged $150 to $250 per engineer per month, with heavy users at $500 to $2,000, which led to a cap of $1,500 per employee per tool.
Falling prices are not the whole story
Unit prices are dropping fast. Epoch AI found that the price of reaching a fixed capability level fell between 9 and 900 times per year, depending on the benchmark, and warned the fastest drops may not last. But when one task uses 5 to 30 times more tokens, volume can outrun the discount.
For enterprises this is also a governance question: who owns the budget, how spend is attributed to teams, and how to keep costs predictable when an agent’s number of steps cannot be known in advance.
Design elements that keep token use in check
Good tokenomics is mostly design, not discount hunting. Nine levers, roughly in order of payoff:
- Route by difficulty. Send easy steps to a small, cheap model and keep the frontier model for hard ones. In the price table above, the budget model costs 20 times less on input than a mid-range one. MindStudio estimates task-based routing saves 40 to 70%, though that is the author’s estimate, not a measured study.
- Cache what repeats. Instructions and reference text that never change can be cached. On Anthropic’s API, cache reads cost 10% of the base input price on most models and 5% on Claude Sonnet 5.5 and Opus 5.5. One reported case study cut LLM cost 59% by lifting its cache hit rate from 7% to 84%, per Spheron.
- Trim the context. Send only what the step needs. Retrieve the relevant snippet instead of the whole document, and summarize old conversation history.
- Put tools on a diet. Every tool description is re-sent on every call. Cisco reports that loading only the tool definitions a sub-task needs has cut token use by over 98% in some cases. Keep tool outputs short and structured too.
- Package know-how as skills. A skill loads just its name and description until the task needs it, instead of stuffing every instruction into every request.
- Cap the loop. Set a maximum number of steps, tokens and retries per task, and stop gracefully. Spheron notes that retries can outweigh the rest of a task’s token cost.
- Batch the non-urgent. An overnight report does not need an instant answer. Providers offer batch processing at a lower price for work that can wait.
- Measure everything. Meter tokens per agent, per task and per team. Track cost per resolution and token yield, not just the monthly total.
- Add guardrails. Budgets, alerts and circuit breakers stop a runaway agent before the invoice does.
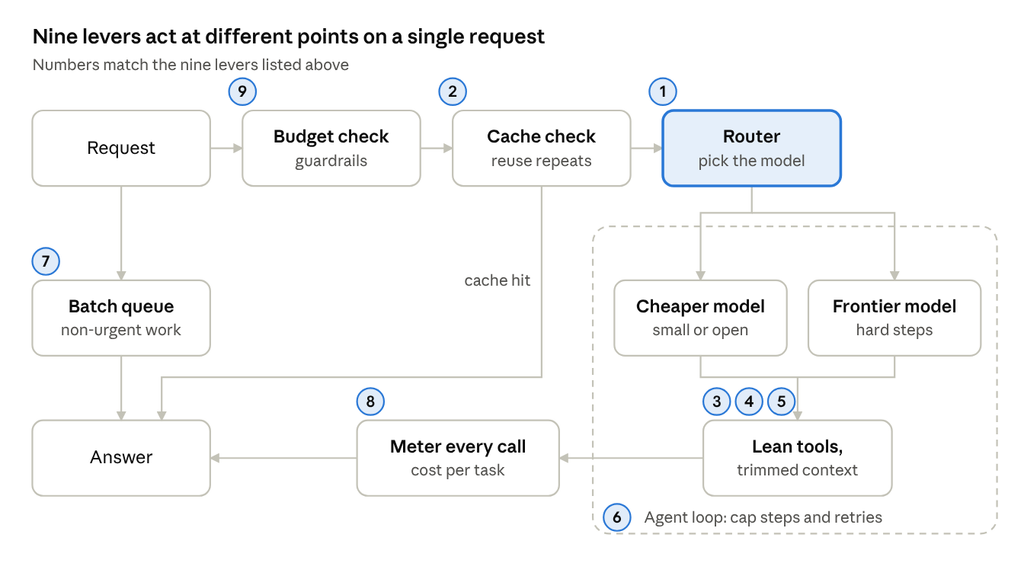
Read it from the top left: guardrails and the cache can stop or answer a request before any model is called, the router sends each step to the cheapest model that can handle it, and the loop stays inside a cap.
How open-weight and open-source models help
Open-weight models publish their trained “weights”, so anyone can download and run them, or pick from many hosting companies. Strictly “open source” also shares training code and data, which is rarer. For tokenomics the practical point is the same: you gain a choice over who runs the model and what it costs.
Price and quality, side by side
OpenRouter’s June 2026 review of the open-weight models that matter lists these average prices and Artificial Analysis Intelligence Index scores (higher is better):
| Open-weight model | Intelligence Index | Input ($ per 1M tokens) | Output ($ per 1M tokens) |
|---|---|---|---|
| DeepSeek V4 Flash | 40 | 0.054 | 0.242 |
| MiniMax M3 | 44 | 0.098 | 1.21 |
| Nemotron 3 Ultra | 48 | 0.423 | 2.61 |
| GLM 5.2 | 51 | 0.447 | 3.31 |
The same article puts the top open model, GLM 5.2, about 5 points below Claude Fable 5 on that index. It also reports DeepSeek V4 Pro at 80.6% on SWE-bench Verified, a coding test, which it calls on par with GPT-5.5-class models. Against the price table earlier, DeepSeek V4 Flash’s first-party output rate of $0.28 per million tokens is about 180 times below Claude Fable 5.1’s $50.
Two caveats from that review: DeepSeek’s own API retains and trains on user data, and Western hosts that do not train on your data charge about double.
Same workload, very different bills
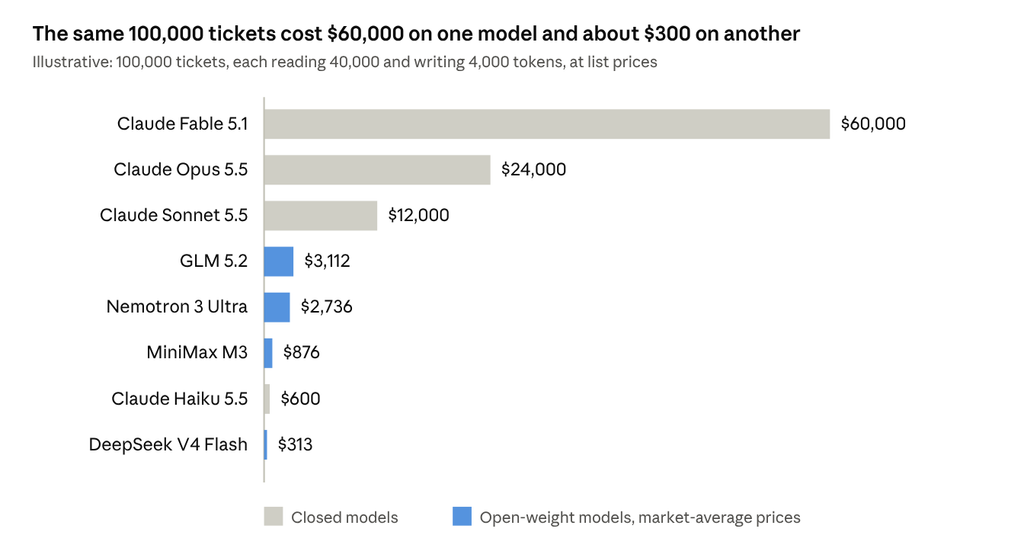
The chart reuses the support ticket from earlier. Quality is not equal across these models and open-weight prices are market averages, so read it as a sense of scale, not a buying guide.
Where they help
- Lower unit cost. The table speaks for itself, especially for high-volume work.
- Right-sizing. A small model can classify emails or extract fields for a fraction of a frontier model’s price, which pairs well with routing.
- Control. Running a model in your own cloud keeps sensitive data in-house, which matters in regulated industries.
- Predictable spend. Self-hosting turns a per-token meter into an infrastructure cost, easier to budget when traffic is steady.
- Efficiency tuning. You can apply caching, batching and model compression yourself, rather than waiting for a provider to.
Read the fine print
Cheaper per token is not always cheaper per task. In an example from investor Bindu Reddy, reported by MindStudio, Kimi K3 costs about half of GPT 5.1 per token but needs more tokens, so a completed task costs 84 cents against 96 cents, only about 12.5% less.
Self-hosting has its own bill. Layer3 Labs warns that idle rented GPUs quietly drain budgets, that engineering time is often the largest yearly line item, and that you should stress-test costs at 30 to 50% GPU utilization, not 100%. Benchmarks also vary: the gap to closed models is small on some coding and knowledge-work tests and wider on the hardest reasoning tasks.
The hybrid pattern
Most teams land on a mix. Open models handle high-volume, well-defined work, frontier models handle the hardest steps, and a router decides between them. It is the routing idea from the previous section with a wider menu.
A simple framework to get started
You do not need to do all nine levers at once. Start with five steps you can finish in a week:
- Measure. Count tokens and cost for one real workflow, end to end. Work out the cost per completed task, not per call.
- Route. Pick the easiest third of the steps and test a cheaper model on them. Keep the better model for the rest.
- Trim. Look at what you send on each call. Cut instructions, history and tool descriptions that the step does not need.
- Cache. Move the unchanging parts, such as instructions and reference text, to the front and turn on caching.
- Cap. Set a limit on steps, retries and spend per task, with an alert when it is close.
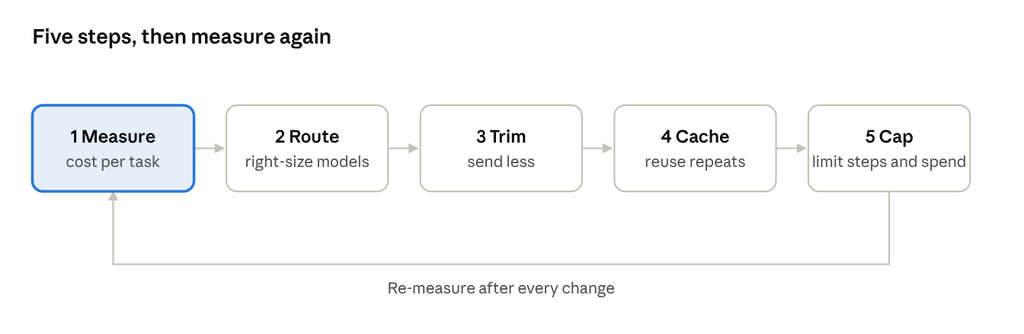
Re-measure after each step. The goal is a lower cost per successful outcome with quality held steady, not the smallest token count.
TL;DR
- What Tokenomics covers: Tokenomics is the economics of AI tokens—how many tokens a task uses, what each costs, and what you get in return, framed as cost, value and efficiency of token consumption.
- What a token is and the key types: A token is a small chunk of text; the main types are input tokens, output tokens, context window, cached tokens, and reasoning tokens, each contributing to cost.
- The real metric: cost per task: Prices per token miss the bigger picture; cost per resolution or per task accounts for token usage across a workflow and is the practical measure of spending.
- Why tokenomics is becoming critical: Agentic systems loop, the context snowball grows with every step, reasoning is billed, and pilots hide the problem, all driving token usage higher in production.
- A simple starting framework to reduce token use: Start with five steps: measure cost per task, route easy steps to cheaper models, trim unnecessary input, cache unchanging content, and cap the loop with limits and alerts.
The Takeaway
Design for cost per outcome from day one. Cheaper tokens help, but they do not replace good design: route work to the right model, send less, reuse what repeats, and put a ceiling on every agent. Teams that treat tokens like any other scarce resource will scale agents with confidence, and the rest will scale surprises.
What is the first workflow in your organization where you would measure cost per task? A worked cost model for a real agent would make a good follow-up.